Microphone Text Input
This mod uses speech recognition technology to enable you to enter text using a microphone and send player messages. Press the key v to perform voice recognition and automatically send a message.
截图

介绍
Microphone Text Input Mod User Documention
Architectury 2.x
Introduction
The Microphone Text Input Mod is a Fabric mod designed for Minecraft clients. It provides speech recognition input
functionality and automatically converts spoken words into text chat messages, enhancing the in – game communication
experience.
Features
- Multiple Modes: Supports different operation modes, including
AUTO_SEND,RELEASE_KEY_TO_SEND, andRELEASE_KEY_TO_INPUT. - Advanced Configuration: Allows users to adjust advanced parameters related to the Whisper library, such as the number of threads, audio context size, and sampling strategy.
Dependencies
| Dependency Name | Fabric | NeoForge |
|——————|——————————————————————|———————————————————————————–|
| Java | 21 | 21 |
| Fabric API | see fabric.mod.json | ❌ |
| Architectury API | ❌ | see neoforge.mods.toml |
| MidnightLib | see fabric.mod.json | see neoforge.mods.toml |
Configuration
Keybinding
| Keybinding Name | Recognize |
|—————–|———————————-|
| Category | key.category.minecraft.mcmti |
| Translation Key | key.mcmti.recognize |
| Default Key | V |
General Settings
| Setting | Translation Key | Field | Type | Default Value | Description |
|—————————|—————————————–|———————————————————-|———————————————-|——————————————|———————————————————————————————|
| GGML Whisper Model | mcmti.midnightconfig.model | me.jaffe2718.mcmti.config.McmtiConfig.model | String | "" | Path to the GGML Whisper model. |
| Language | mcmti.midnightconfig.language | me.jaffe2718.mcmti.config.McmtiConfig.language | String | "en" | Language for speech recognition. |
| Mode | mcmti.midnightconfig.mode | me.jaffe2718.mcmti.config.McmtiConfig.mode | me.jaffe2718.mcmti.config.McmtiConfig.Mode | "RELEASE_KEY_TO_SEND" | Mod’s work mode. |
| Record Cycle (ms) | mcmti.midnightconfig.recordCycleMs | me.jaffe2718.mcmti.config.McmtiConfig.recordCycleMs | int | 5000 | Record cycle in milliseconds. |
| Record Buffer Size (byte) | mcmti.midnightconfig.recordBufferSize | me.jaffe2718.mcmti.config.McmtiConfig.recordBufferSize | int | 1024 | Record buffer size in bytes. |
| Prefix | mcmti.midnightconfig.prefix | me.jaffe2718.mcmti.config.McmtiConfig.prefix | String | "⌈Speech Input⌋" | Prefix added to the recognized text. |
| Draft Input | mcmti.midnightconfig.draftInput | me.jaffe2718.mcmti.config.McmtiConfig.draftInput | boolean | false | Enable draft input. If enabled, the recognized text will be shown in the entry as a draft. |
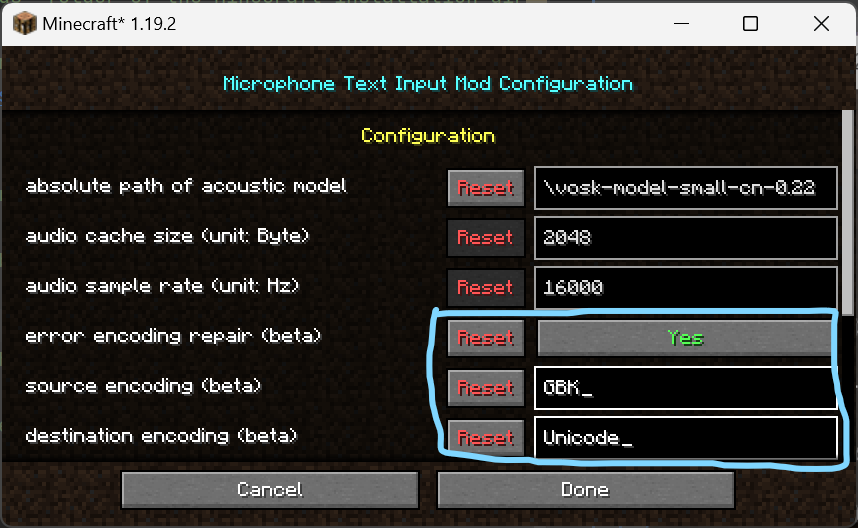
| Encoding Repair | mcmti.midnightconfig.encodingRepair | me.jaffe2718.mcmti.config.McmtiConfig.encodingRepair | boolean | false | Enable encoding repair. |
| Source Encoding | mcmti.midnightconfig.srcEncoding | me.jaffe2718.mcmti.config.McmtiConfig.srcEncoding | String | Charset.defaultCharset().displayName() | Source encoding for text. Applies only if encoding repair is enabled. |
| Destination Encoding | mcmti.midnightconfig.dstEncoding | me.jaffe2718.mcmti.config.McmtiConfig.dstEncoding | String | Charset.defaultCharset().displayName() | Destination encoding for text. Applies only if encoding repair is enabled. |
Advanced Settings
| Setting | Translation Key | Field | Type | Default Value | Description |
|——————————|—————————————————–|———————————————————————-|—————————————————————-|—————|————————————————————————————-|
| Enable Advanced Config | mcmti.midnightconfig.advancedConfig | me.jaffe2718.mcmti.config.McmtiConfig.advancedConfig | boolean | false | Enable advanced configuration. |
| nThreads | mcmti.midnightconfig.nThreads | me.jaffe2718.mcmti.config.McmtiConfig.nThreads | int | 0 | Number of threads to use for the operation of the Whisper model. 0 for max cores. |
| audioCtx | mcmti.midnightconfig.audioCtx | me.jaffe2718.mcmti.config.McmtiConfig.audioCtx | int | 0 | Audio context size for the Whisper model. 0 means use default. |
| nMaxTextCtx | mcmti.midnightconfig.nMaxTextCtx | me.jaffe2718.mcmti.config.McmtiConfig.nMaxTextCtx | int | 16384 | Max tokens to use from past text as prompt for the decoder. |
| offsetMs | mcmti.midnightconfig.offsetMs | me.jaffe2718.mcmti.config.McmtiConfig.offsetMs | int | 0 | Offset in ms to start recording from. |
| durationMs | mcmti.midnightconfig.durationMs | me.jaffe2718.mcmti.config.McmtiConfig.durationMs | int | 0 | Audio duration to process in ms. 0 means use default. |
| translate | mcmti.midnightconfig.translate | me.jaffe2718.mcmti.config.McmtiConfig.translate | boolean | false | Translate the text to the default language. |
| noTimestamps | mcmti.midnightconfig.noTimestamps | me.jaffe2718.mcmti.config.McmtiConfig.noTimestamps | boolean | false | Do not generate timestamps. |
| initialPrompt | mcmti.midnightconfig.initialPrompt | me.jaffe2718.mcmti.config.McmtiConfig.initialPrompt | String | "" | Initial text to use as a prompt for the whisper. |
| noContext | mcmti.midnightconfig.noContext | me.jaffe2718.mcmti.config.McmtiConfig.noContext | boolean | true | Do not use past transcription (if any) as initial prompt for the decoder. |
| singleSegment | mcmti.midnightconfig.singleSegment | me.jaffe2718.mcmti.config.McmtiConfig.singleSegment | boolean | false | Force single segment output (useful for streaming). |
| printSpecial | mcmti.midnightconfig.printSpecial | me.jaffe2718.mcmti.config.McmtiConfig.printSpecial | boolean | false | Print special tokens. |
| printProgress | mcmti.midnightconfig.printProgress | me.jaffe2718.mcmti.config.McmtiConfig.printProgress | boolean | true | Print progress information. |
| printRealtime | mcmti.midnightconfig.printRealtime | me.jaffe2718.mcmti.config.McmtiConfig.printRealtime | boolean | false | Print results from within whisper.cpp (avoid it, use callback instead). |
| printTimestamps | mcmti.midnightconfig.printTimestamps | me.jaffe2718.mcmti.config.McmtiConfig.printTimestamps | boolean | true | Print timestamps for each text segment when printing realtime. |
| suppressBlank | mcmti.midnightconfig.suppressBlank | me.jaffe2718.mcmti.config.McmtiConfig.suppressBlank | boolean | true | Decoder option. |
| suppressNonSpeechTokens | mcmti.midnightconfig.suppressNonSpeechTokens | me.jaffe2718.mcmti.config.McmtiConfig.suppressNonSpeechTokens | boolean | true | Tokenizer option. |
| temperature | mcmti.midnightconfig.temperature | me.jaffe2718.mcmti.config.McmtiConfig.temperature | float | 0.0f | Initial decoding temperature. |
| maxInitialTs | mcmti.midnightconfig.maxInitialTs | me.jaffe2718.mcmti.config.McmtiConfig.maxInitialTs | float | 1.0f | Maximum initial timestamp. |
| lengthPenalty | mcmti.midnightconfig.lengthPenalty | me.jaffe2718.mcmti.config.McmtiConfig.lengthPenalty | float | -1.0f | Length penalty. |
| temperatureInc | mcmti.midnightconfig.temperatureInc | me.jaffe2718.mcmti.config.McmtiConfig.temperatureInc | float | 0.4f | Temperature increment. |
| entropyThold | mcmti.midnightconfig.entropyThold | me.jaffe2718.mcmti.config.McmtiConfig.entropyThold | float | 2.4f | Entropy threshold (similar to OpenAI’s “compression_ratio_threshold”). |
| logprobThold | mcmti.midnightconfig.logprobThold | me.jaffe2718.mcmti.config.McmtiConfig.logprobThold | float | -1.0f | Log probability threshold. |
| noSpeechThold | mcmti.midnightconfig.noSpeechThold | me.jaffe2718.mcmti.config.McmtiConfig.noSpeechThold | float | 0.6f | No speech threshold. |
| greedyBestOf | mcmti.midnightconfig.greedyBestOf | me.jaffe2718.mcmti.config.McmtiConfig.greedyBestOf | int | -1 | Specific to greedy sampling strategy. |
| beamSearchBeamSize | mcmti.midnightconfig.beamSearchBeamSize | me.jaffe2718.mcmti.config.McmtiConfig.beamSearchBeamSize | int | 2 | Specific to bean search sampling strategy. |
| beamSearchPatience | mcmti.midnightconfig.beamSearchPatience | me.jaffe2718.mcmti.config.McmtiConfig.beamSearchPatience | float | -1.0f | Specific to bean search sampling strategy. |
| grammar | mcmti.midnightconfig.grammar | me.jaffe2718.mcmti.config.McmtiConfig.grammar | String | "" | Grammar file path. Empty means no grammar. |
| grammarPenalty | mcmti.midnightconfig.grammarPenalty | me.jaffe2718.mcmti.config.McmtiConfig.grammarPenalty | float | 100.0f | Penalty for non grammar tokens. |
| whisperSamplingStrategy | mcmti.midnightconfig.whisperSamplingStrategy | me.jaffe2718.mcmti.config.McmtiConfig.whisperSamplingStrategy | io.github.freshsupasulley.whisperjni.WhisperSamplingStrategy | BEAM_SEARCH | The WhisperContext enum to configure whisper’s sampling strategy. |
| vad | mcmti.midnightconfig.vad | me.jaffe2718.mcmti.config.McmtiConfig.vad | boolean | false | Enable VAD (Voice Activity Detection). |
| vad__max_speech_duration_s | mcmti.midnightconfig.vad__max_speech_duration_s | me.jaffe2718.mcmti.config.McmtiConfig.vad__max_speech_duration_s | float | 0f | Max duration of a speech segment before forcing a new segment. |
| vad__min_silence_duration_ms | mcmti.midnightconfig.vad__min_silence_duration_ms | me.jaffe2718.mcmti.config.McmtiConfig.vad__min_silence_duration_ms | int | 0 | Min silence duration to consider speech as ended. |
| vad__min_speech_duration_ms | mcmti.midnightconfig.vad__min_speech_duration_ms | me.jaffe2718.mcmti.config.McmtiConfig.vad__min_speech_duration_ms | int | 0 | Min duration for a valid speech segment. |
| vad__samples_overlap | mcmti.midnightconfig.vad__samples_overlap | me.jaffe2718.mcmti.config.McmtiConfig.vad__samples_overlap | float | 0f | Overlap in seconds when copying audio samples from speech segment. |
| vad__speech_pad_ms | mcmti.midnightconfig.vad__speech_pad_ms | me.jaffe2718.mcmti.config.McmtiConfig.vad__speech_pad_ms | int | 0 | Padding added before and after speech segments. |
| vad__threshold | mcmti.midnightconfig.vad__threshold | me.jaffe2718.mcmti.config.McmtiConfig.vad__threshold | float | 0f | Probability threshold to consider as speech. |
| vad_model_path | mcmti.midnightconfig.vad_model_path | me.jaffe2718.mcmti.config.McmtiConfig.vad_model_path | String | "" | Path to the VAD model. Empty means use default. |
| useCustomDynamicLib | mcmti.midnightconfig.useCustomDynamicLib | me.jaffe2718.mcmti.config.McmtiConfig.useCustomDynamicLib | boolean | false | Enable using custom dynamic library for Whisper. |
| customDynamicLibDir | mcmti.midnightconfig.customDynamicLibDir | me.jaffe2718.mcmti.config.McmtiConfig.customDynamicLibDir | String | "" | Custom dynamic link library directory for Whisper. |
- For more info, see WhisperFullParams.java
WARNING: Activating the advanced configuration will change the default parameters of the Whisper model configuration,
which will have a critical impact on the speech recognition results. Inappropriate configuration of advanced
parameters can lead to problems such as speech recognition failure, high computer resource usage, and program crashes.
Please use with caution.
Usage
- Install the mod and download the GGML Whisper model.
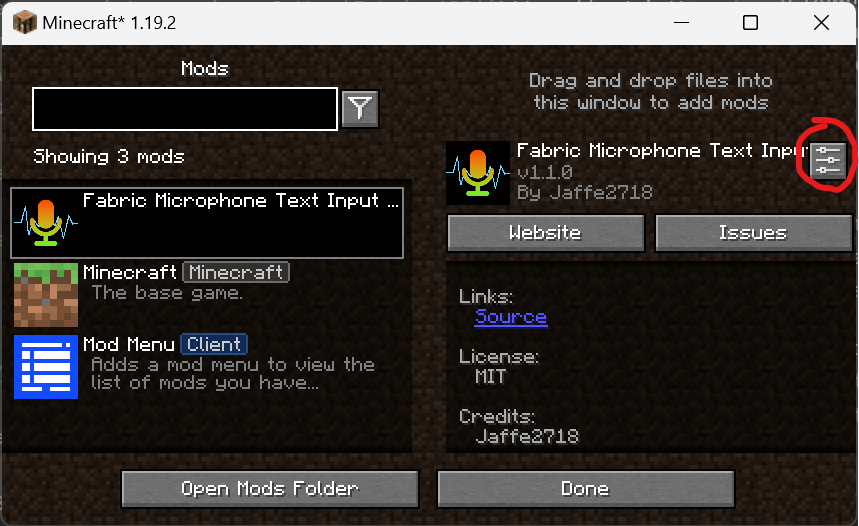
- Configure the mod according to your needs in the configuration menu.
- Use the keybinding you set (default is
V) to start recording and speech recognition. - If the mode is set to
AUTO_SEND, the recognized text will be automatically sent as a chat message. If set toRELEASE_KEY_TO_SENDorRELEASE_KEY_TO_INPUT, follow the corresponding key – release actions.
Use VAD
If you want to use VAD (Voice Activity Detection), you need to download VAD model,
enable the advanced configuration and set the vad_model_path to the path of the VAD model in the configuration menu.
Custom Dynamic Library
- Download the custom dynamic library from Jaffe2718/whisper-jni and extract the files.
- Enable the advanced configuration and set the
useCustomDynamicLibtotruein the configuration menu. - Set the
customDynamicLibDirto the directory where the custom dynamic library is located in the configuration menu. - If you want to use the dynamic library which is supported vulkan, check your check that your computer has drivers and libraries running Vulkan installed.
vulkaninfo- If you want to use CUDA, check that your computer has drivers and libraries running CUDA installed.
nvidia-smiFor Linux, you need to install CUDA Toolkit >= 12.4.0 and configure the environment variables.
For Windows, if the game crashes, you have to force the game to use the Java >= 25, see Jaffe2718/whisper-jni/v0.5.6
Troubleshooting
- Crash on Startup: Please check the compatibility and version of your use of the dynamic link library. You can disable the advanced configuration and set the
useCustomDynamicLibtofalseto use the default dynamic library (CPU version). - Audio Input Device Load Failed: Please check if Java has access to the audio input device.
- Whisper Model Load Failed: Make sure the path to the GGML Whisper model is correct.
Contributing
If you’d like to contribute to this project, please feel free to submit issues or pull requests
on GitHub.
常见问题
Microphone Text Input 支持哪些 Minecraft 版本?
Microphone Text Input 支持 Minecraft Java 版 1.19.2–26.1.2,共 22 个版本,可用的加载器:Fabric / Forge / NeoForge / Quilt。下载时注意选择和你游戏版本一致的文件。
Microphone Text Input 怎么安装?
先用 PCL2 或 HMCL 启动器安装对应版本的 Fabric / Forge / NeoForge / Quilt,再把下载的 .jar 文件放进游戏目录的 mods 文件夹,重新启动游戏即可。开启了版本隔离的,mods 文件夹在 versions/版本名 下面。运行环境:仅客户端。
Jaffe2718 的其他作品
查看全部 →
Sniper Rifle (狙击枪模组 )
支持Minecraft 1.19.1和1.19.2的Fabric狙击枪模组 详见https://github.com/Jaffe2718/Fabric-Sniper-Rifle-1.19.2-MDK
Command Debug Service
This is a mod that provides a method to execute and debug Minecraft commands by external programs. It is used to be a command debug connect kit between Minecraft and external programs.

Steroid Planet
Steroid Planet adds a high-stakes bodybuilding system to Minecraft! Unlock tiered steroids (I/II/III) to boost muscle mass, reduce body fat, and chase extreme milestones.
Steroid Planet
Steroid Planet adds a high-stakes bodybuilding system to Minecraft! Unlock tiered steroids (I/II/III) to boost muscle mass, reduce body fat, and chase extreme milestones.
评论
登录后评论和评分